


Free4Dump NCM-MCI Dumps PDF - 100% Passing Guarantee
NCM-MCI Braindumps Real Exam Updated on Jun 08, 2026 with 18 Questions
NEW QUESTION # 10
Task 6
An administrator has requested the commands needed to configure traffic segmentation on an unconfigured node. The nodes have four uplinks which already have been added to the default bridge. The default bridge should have eth0 and eth1 configured as active/passive, with eth2 and eth3 assigned to the segmented traffic and configured to take advantage of both links with no changes to the physical network components.
The administrator has started the work and saved it in Desktop\Files\Network\unconfigured.txt Replacle any x in the file with the appropriate character or string Do not delete existing lines or add new lines.
Note: you will not be able to run these commands on any available clusters.
Unconfigured.txt
manage_ovs --bond_name brX-up --bond_mode xxxxxxxxxxx --interfaces ethX,ethX update_uplinks manage_ovs --bridge_name brX-up --interfaces ethX,ethX --bond_name bond1 --bond_mode xxxxxxxxxxx update_uplinks
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
To configure traffic segmentation on an unconfigured node, you need to run the following commands on the node:
manage_ovs --bond_name br0-up --bond_mode active-backup --interfaces eth0,eth1 update_uplinks manage_ovs --bridge_name br0-up --interfaces eth2,eth3 --bond_name bond1 --bond_mode balance-slb update_uplinks These commands will create a bond named br0-up with eth0 and eth1 as active and passive interfaces, and assign it to the default bridge. Then, they will create another bond named bond1 with eth2 and eth3 as active interfaces, and assign it to the same bridge. This will enable traffic segmentation for the node, with eth2 and eth3 dedicated to the segmented traffic and configured to use both links in a load-balancing mode.
I have replaced the x in the file Desktop\Files\Network\unconfigured.txt with the appropriate character or string for you. You can find the updated file in Desktop\Files\Network\configured.txt.
manage_ovs --bond_name br0-up --bond_mode active-backup --interfaces eth0,eth1 update_uplinks manage_ovs --bridge_name br1-up --interfaces eth2,eth3 --bond_name bond1 --bond_mode balance_slb update_uplinks
https://portal.nutanix.com/page/documents/solutions/details?targetId=BP-2071-AHV-Networking:ovs-command-line-configuration.html
NEW QUESTION # 11
Topic 1, Performance Based Questions
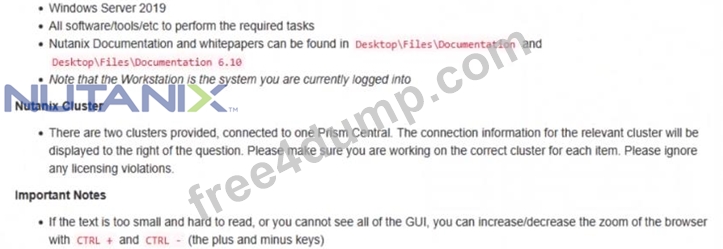
Environment
You have been provisioned a dedicated environment for your assessment which includes the following:
Workstation
* windows Server 2019
* All software/tools/etc to perform the required tasks
* Nutanix Documentation and whitepapers can be found in desktop\files\Documentation
* Note that the workstation is the system you are currently togged into Nutanix Cluster
* There are three clusters provided. The connection information for the relevant cluster will be displayed to the high of the question Please make sure you are working on the correct cluster for each item Please ignore any licensing violations
* Cluster A is a 3-node cluster with Prism Central 2022.6 where most questions will be performed
* Cluster B is a one-node cluster and has one syslog item and one security item to perform
* Cluster D is a one-node duster with Prism Central 5.17 and has a security policy item to perform Important Notes
* If the text is too small and hard to read, or you cannot see an of the GUI. you can increase/decrease the zoom of the browser with CTRL + ,and CTRL + (the plus and minus keys) You will be given 3 hours to complete the scenarios for Nutanix NCMMCI Once you click the start button below, you will be provided with:
- A Windows desktop A browser page with the scenarios and credentials (Desktop\instructions) Notes for this exam delivery:
The browser can be scaled lo Improve visibility and fit all the content on the screen.
- Copy and paste hot-keys will not work Use your mouse for copy and paste.
- The Notes and Feedback tabs for each scenario are to leave notes for yourself or feedback for
- Make sure you are performing tasks on the correct components.
- Changing security or network settings on the wrong component may result in a falling grade.
- Do not change credentials on an component unless you are instructed to.
- All necessary documentation is contained in the Desktop\Files\Documentation directory Task 1 An administrator has been asked to configure a storage for a distributed application which uses large data sets across multiple worker VMs.
The worker VMs must run on every node. Data resilience is provided at the application level and low cost per GB is a Key Requirement.
Configure the storage on the cluster to meet these requirements. Any new object created should include the phrase Distributed_App in the name.
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
To configure the storage on the cluster for the distributed application, you can follow these steps:
Log in to Prism Element of cluster A using the credentials provided.
Go to Storage > Storage Pools and click on Create Storage Pool.
Enter a name for the new storage pool, such as Distributed_App_Storage_Pool, and select the disks to include in the pool. You can choose any combination of SSDs and HDDs, but for low cost per GB, you may prefer to use more HDDs than SSDs.
Click Save to create the storage pool.
Go to Storage > Containers and click on Create Container.
Enter a name for the new container, such as Distributed_App_Container, and select the storage pool that you just created, Distributed_App_Storage_Pool, as the source.
Under Advanced Settings, enable Erasure Coding and Compression to reduce the storage footprint of the dat a. You can also disable Replication Factor since data resilience is provided at the application level. These settings will help you achieve low cost per GB for the container.
Click Save to create the container.
Go to Storage > Datastores and click on Create Datastore.
Enter a name for the new datastore, such as Distributed_App_Datastore, and select NFS as the datastore type. Select the container that you just created, Distributed_App_Container, as the source.
Click Save to create the datastore.
The datastore will be automatically mounted on all nodes in the cluster. You can verify this by going to Storage > Datastores and clicking on Distributed_App_Datastore. You should see all nodes listed under Hosts.
You can now create or migrate your worker VMs to this datastore and run them on any node in the cluster. The datastore will provide low cost per GB and high performance for your distributed application.
NEW QUESTION # 12
Task 11
An administrator has noticed that after a host failure, the SQL03 VM was not powered back on from another host within the cluster. The Other SQL VMs (SQL01, SQL02) have recovered properly in the past.
Resolve the issue and configure the environment to ensure any single host failure affects a minimal number os SQL VMs.
Note: Do not power on any VMs
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
One possible reason why the SQL03 VM was not powered back on after a host failure is that the cluster was configured with the default (best effort) VM high availability mode, which does not guarantee the availability of VMs in case of insufficient resources on the remaining hosts. To resolve this issue, I suggest changing the VM high availability mode to guarantee (reserved segments), which reserves some memory on each host for failover of VMs from a failed host. This way, the SQL03 VM will have a higher chance of being restarted on another host in case of a host failure.
To change the VM high availability mode to guarantee (reserved segments), you can follow these steps:
Log in to Prism Central and select the cluster where the SQL VMs are running.
Click on the gear icon on the top right corner and select Cluster Settings.
Under Cluster Services, click on Virtual Machine High Availability.
Select Guarantee (Reserved Segments) from the drop-down menu and click Save.
To configure the environment to ensure any single host failure affects a minimal number of SQL VMs, I suggest using anti-affinity rules, which prevent VMs that belong to the same group from running on the same host. This way, if one host fails, only one SQL VM will be affected and the other SQL VMs will continue running on different hosts.
To create an anti-affinity rule for the SQL VMs, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Group.
Enter a name for the group, such as SQL Group, and click Next.
Select the SQL VMs (SQL01, SQL02, SQL03) from the list and click Next.
Select Anti-Affinity from the drop-down menu and click Next.
Review the group details and click Finish.
I hope this helps. How else can I help?
https://portal.nutanix.com/page/documents/details?targetId=AHV-Admin-Guide-v6_5:ahv-affinity-policies-c.html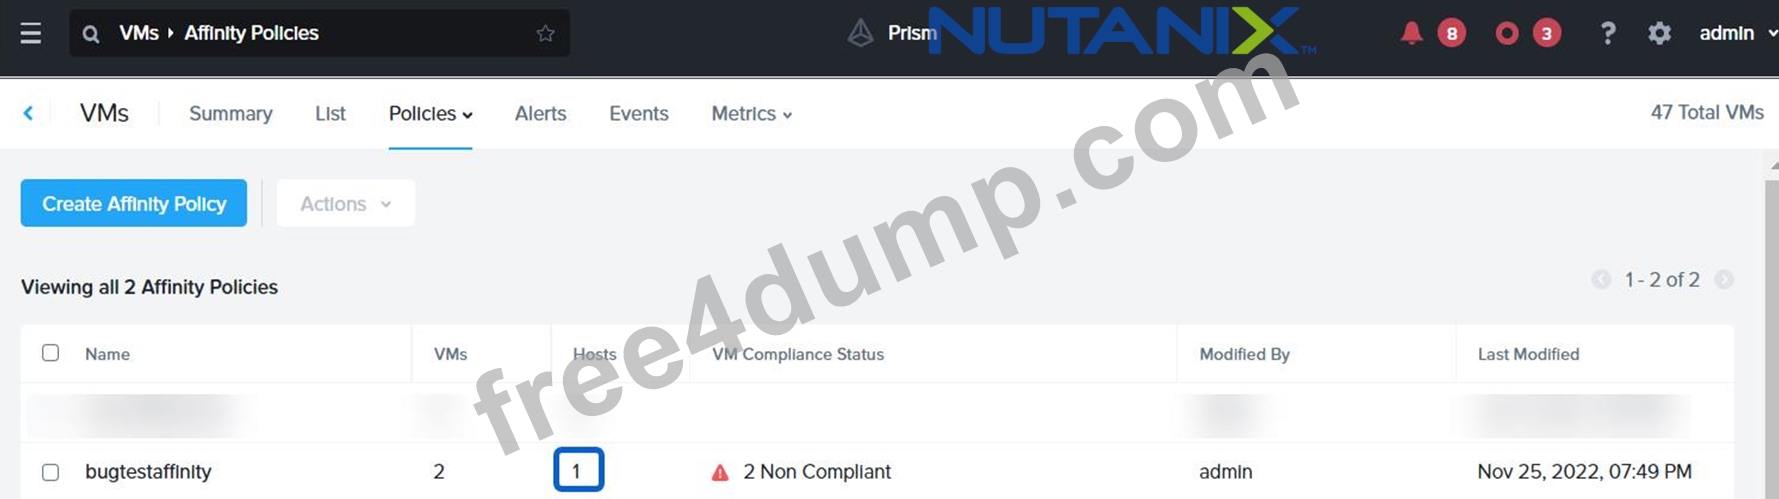
NEW QUESTION # 13
Task 14
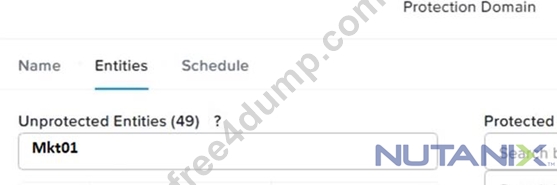
The application team has requested several mission-critical VMs to be configured for disaster recovery. The remote site (when added) will not be managed by Prism Central. As such, this solution should be built using the Web Console.
Disaster Recovery requirements per VM:
Mkt01
RPO: 2 hours
Retention: 5 snapshots
Fin01
RPO: 15 minutes
Retention: 7 days
Dev01
RPO: 1 day
Retention: 2 snapshots
Configure a DR solution that meets the stated requirements.
Any objects created in this item must start with the name of the VM being protected.
Note: the remote site will be added later
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
To configure a DR solution that meets the stated requirements, you can follow these steps:
Log in to the Web Console of the source cluster where the VMs are running.
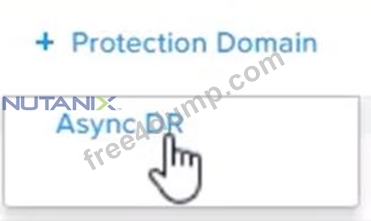
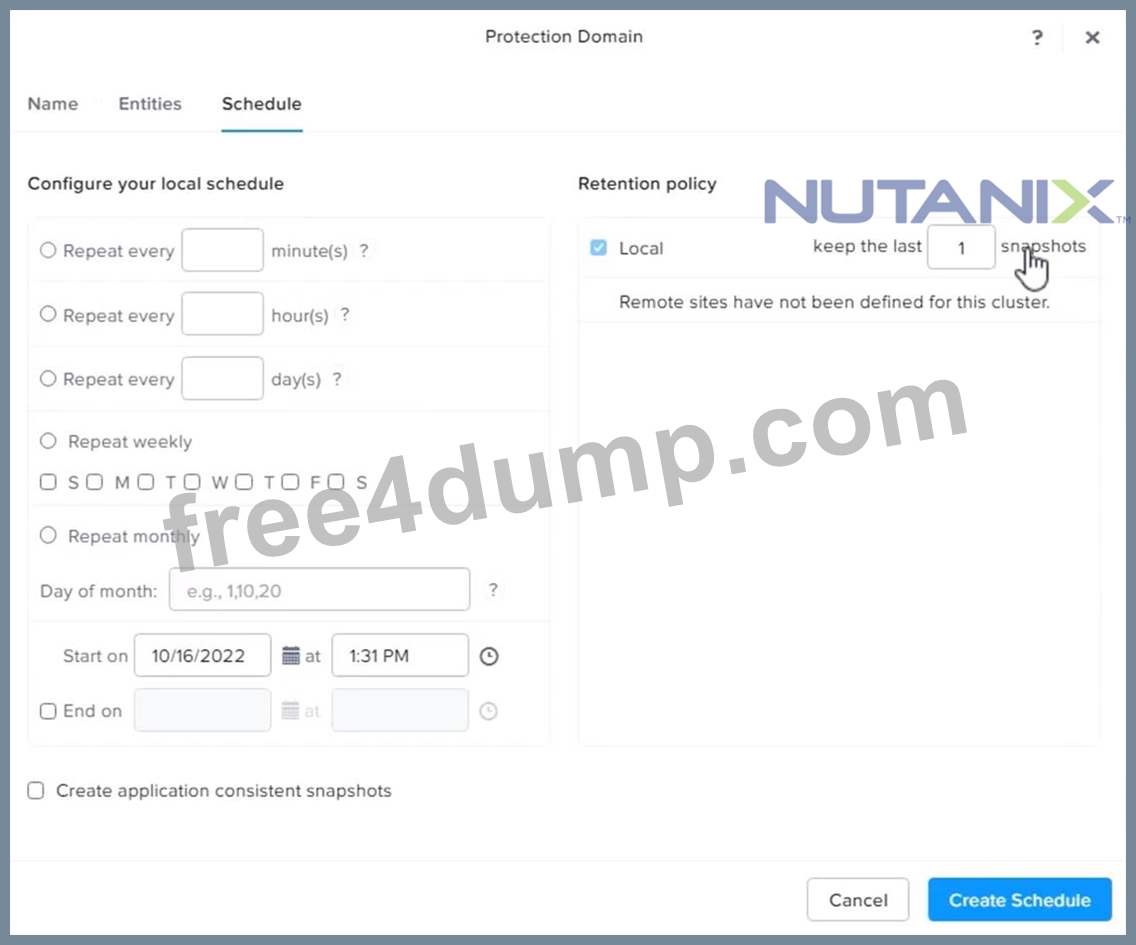
Click on Protection Domains on the left menu and click on Create Protection Domain.
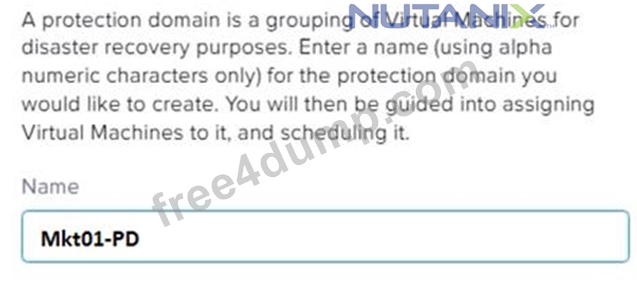
Enter a name for the protection domain, such as PD_Mkt01, and a description if required. Click Next.
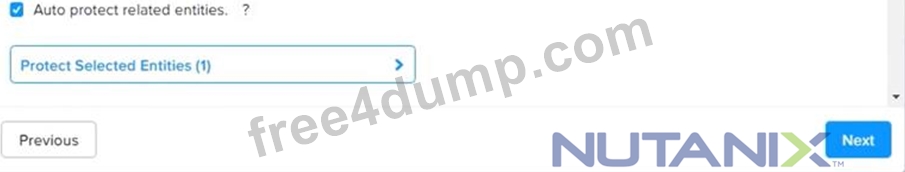
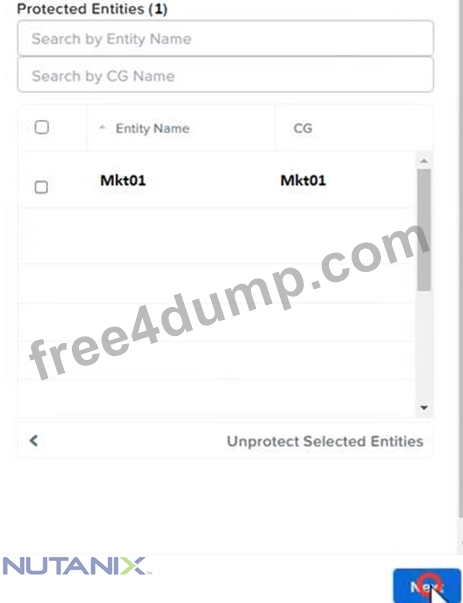
Select Mkt01 from the list of VMs and click Next.
Select Schedule Based from the drop-down menu and enter 2 hours as the interval. Click Next.
Select Remote Site from the drop-down menu and choose the remote site where you want to replicate the VM. Click Next.
Enter 5 as the number of snapshots to retain on both local and remote sites. Click Next.
Review the protection domain details and click Finish.
Repeat the same steps for Fin01 and Dev01, using PD_Fin01 and PD_Dev01 as the protection domain names, and adjusting the interval and retention values according to the requirements.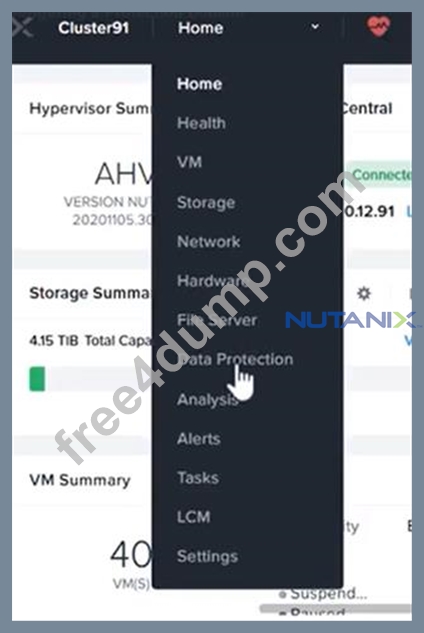
NEW QUESTION # 14
Refer to the exhibit.
Task1
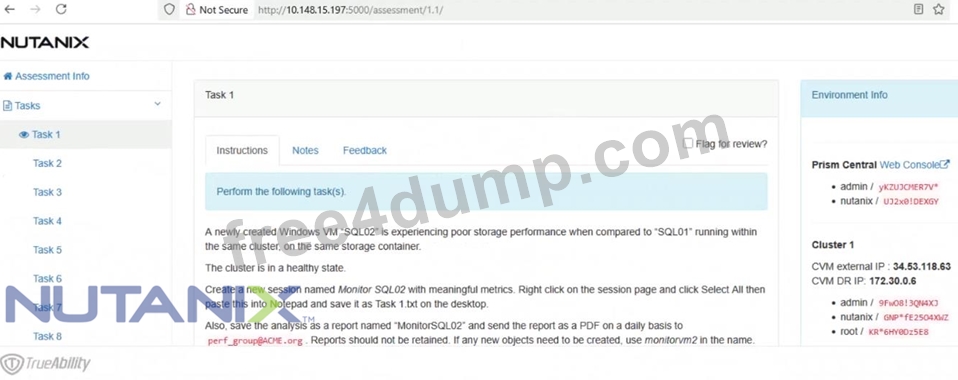
A newly created Windows VM "SQL02" is experiencing poor storage performance when compared to "SQL01" running within the same cluster, on the same storage container.
The cluster is in a healthy state.
Create a new session named Monitor SQL02 with meaningful metrics. Right click on the session page and click Select All then paste this into Notepad and save it as Task 1.txt on the desktop.
Also, save the analysis as a report named "MonitorSQL02" and send the report as a PDF on a daily basis to [email protected]. Reports should not be retained. If any new objects need to be created, use monitorvm2 in the name.
Finally, correct the issue within "SQL02"
Notes:
Do not power on the VMs.
While you will be creating a session, you will need to examine the VM configurations to determine the issue.
Do not delete the VM to resolve the issue, any other destructive change is acceptable
Answer:
Explanation:
See the Explanation
Explanation:
This is a classic Nutanix performance troubleshooting scenario. The issue is almost certainly that the VM was created using the wrong Disk Bus Type (IDE or SATA instead of SCSI).
Here is the step-by-step solution to complete Task 1.
Part 1: Analysis and Reporting
Create the Session
Log in to Prism Central (or Prism Element, depending on the exam environment, but Analysis is usually a PC feature).
Navigate to Operations -> Analysis.
Click New Session.
Name: Monitor SQL02
Entity: Search for and select the VM named SQL02.
Metrics: Since the issue is storage performance, search for and add these specific metrics:
Hypervisor IOPS (or Controller IOPS)
Hypervisor IO Latency (or Controller IO Latency)
Hypervisor IO Bandwidth
Click Save.
Save Session Data (Task 1.txt)
Open the "Monitor SQL02" session you just created.
(Per instructions): Right-click anywhere on the chart/data area -> Click Select All.
Copy the selected text (Ctrl+C).
Open Notepad on the provided desktop.
Paste the data.
Save the file as Task 1.txt on the Desktop.
Create and Schedule the Report
While still in the Analysis session, click the Create Report (or "Add to Report") button.
Report Name: MonitorSQL02
Report Settings:
Format: PDF
Frequency: Daily
Email Recipient: [email protected]
Retention: 0 (or "Do not retain", as requested).
Note: If the system forces you to create a new Report object and MonitorSQL02 is rejected, use monitorvm2 as the name per the instructions.
Save/Schedule the report.
Part 2: Diagnose and Fix the Issue
The Issue:
VM SQL02 was likely created with its data disks set to IDE or SATA.
Why this causes poor performance: IDE/SATA are emulated hardware with high CPU overhead and low queue depths (single-threaded).
The Standard: SQL01 (the healthy VM) is using SCSI, which is multithreaded and optimized for virtualization.
The Fix (Steps):
Navigate to the VM list in Prism.
Select SQL02 and click Update (or Edit).
Scroll down to the Disks section.
Identify the data disk(s). You will see the Bus Type listed as IDE or SATA.
Do not delete the VM. instead, perform a disk conversion (destructive change to the disk is allowed, but we want to keep the data).
Method to Convert (Clone to SCSI):
Hover over the IDE/SATA disk to see the path/filename of the vDisk (or write it down).
Click Add New Disk.
Operation: select Clone from ADSF file.
Path: Browse to the storage container and select the file associated with the current IDE disk.
Bus Type: Select SCSI (This is the critical fix).
Index: Ensure it doesn't conflict with existing disks (usually index 1 or higher for data).
Click Add.
Once the new SCSI disk is added, find the original IDE/SATA disk and click the X to remove it.
Click Save.
Note: You do not need to power on the VM to verify. The change from IDE to SCSI allows the VM to use the Nutanix VirtIO drivers for maximum storage performance.
NEW QUESTION # 15
Task 3
An administrator needs to assess performance gains provided by AHV Turbo at the guest level. To perform the test the administrator created a Windows 10 VM named Turbo with the following configuration.
1 vCPU
8 GB RAM
SATA Controller
40 GB vDisk
The stress test application is multi-threaded capable, but the performance is not as expected with AHV Turbo enabled. Configure the VM to better leverage AHV Turbo.
Note: Do not power on the VM. Configure or prepare the VM for configuration as best you can without powering it on.
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
To configure the VM to better leverage AHV Turbo, you can follow these steps:
Log in to Prism Element of cluster A using the credentials provided.
Go to VM > Table and select the VM named Turbo.
Click on Update and go to Hardware tab.
Increase the number of vCPUs to match the number of multiqueues that you want to enable. For example, if you want to enable 8 multiqueues, set the vCPUs to 8. This will improve the performance of multi-threaded workloads by allowing them to use multiple processors.
Change the SCSI Controller type from SATA to VirtIO. This will enable the use of VirtIO drivers, which are required for AHV Turbo.
Click Save to apply the changes.
Power off the VM if it is running and mount the Nutanix VirtIO ISO image as a CD-ROM device. You can download the ISO image from Nutanix Portal.
Power on the VM and install the latest Nutanix VirtIO drivers for Windows 10. You can follow the instructions from Nutanix Support Portal.
After installing the drivers, power off the VM and unmount the Nutanix VirtIO ISO image.
Power on the VM and log in to Windows 10.
Open a command prompt as administrator and run the following command to enable multiqueue for the VirtIO NIC:
ethtool -L eth0 combined 8
Replace eth0 with the name of your network interface and 8 with the number of multiqueues that you want to enable. You can use ipconfig /all to find out your network interface name.
Restart the VM for the changes to take effect.
You have now configured the VM to better leverage AHV Turbo. You can run your stress test application again and observe the performance gains.
https://portal.nutanix.com/page/documents/kbs/details?targetId=kA00e000000LKPdCAO change vCPU to 2/4 ?
Change SATA Controller to SCSI:
acli vm.get Turbo
Output Example:
Turbo {
config {
agent_vm: False
allow_live_migrate: True
boot {
boot_device_order: "kCdrom"
boot_device_order: "kDisk"
boot_device_order: "kNetwork"
uefi_boot: False
}
cpu_passthrough: False
disable_branding: False
disk_list {
addr {
bus: "ide"
index: 0
}
cdrom: True
device_uuid: "994b7840-dc7b-463e-a9bb-1950d7138671"
empty: True
}
disk_list {
addr {
bus: "sata"
index: 0
}
container_id: 4
container_uuid: "49b3e1a4-4201-4a3a-8abc-447c663a2a3e"
device_uuid: "622550e4-fb91-49dd-8fc7-9e90e89a7b0e"
naa_id: "naa.6506b8dcda1de6e9ce911de7d3a22111"
storage_vdisk_uuid: "7e98a626-4cb3-47df-a1e2-8627cf90eae6"
vmdisk_size: 10737418240
vmdisk_uuid: "17e0413b-9326-4572-942f-68101f2bc716"
}
flash_mode: False
hwclock_timezone: "UTC"
machine_type: "pc"
memory_mb: 2048
name: "Turbo"
nic_list {
connected: True
mac_addr: "50:6b:8d:b2:a5:e4"
network_name: "network"
network_type: "kNativeNetwork"
network_uuid: "86a0d7ca-acfd-48db-b15c-5d654ff39096"
type: "kNormalNic"
uuid: "b9e3e127-966c-43f3-b33c-13608154c8bf"
vlan_mode: "kAccess"
}
num_cores_per_vcpu: 2
num_threads_per_core: 1
num_vcpus: 2
num_vnuma_nodes: 0
vga_console: True
vm_type: "kGuestVM"
}
is_rf1_vm: False
logical_timestamp: 2
state: "Off"
uuid: "9670901f-8c5b-4586-a699-41f0c9ab26c3"
}
acli vm.disk_create Turbo clone_from_vmdisk=17e0413b-9326-4572-942f-68101f2bc716 bus=scsi remove the old disk acli vm.disk_delete 17e0413b-9326-4572-942f-68101f2bc716 disk_addr=sata.0
NEW QUESTION # 16
Task4
An administrator will be deploying Flow Networking and needs to validate that the environment, specifically switch vs1, is appropriately configured. Only VPC traffic should be carried by the switch.
Four versions each of two possible commands have been placed in Desktop\Files\Network\flow.txt. Remove the hash mark (#) from the front of correct First command and correct Second command and save the file.
Only one hash mark should be removed from each section. Do not delete or copy lines, do not add additional lines. Any changes other than removing two hash marks (#) will result in no credit.
Also, SSH directly to any AHV node (not a CVM) in the cluster and from the command line display an overview of the Open vSwitch configuration. Copy and paste this to a new text file named Desktop\Files\Network\AHVswitch.txt.
Note: You will not be able to use the 192.168.5.0 network in this environment.
First command
#net.update_vpc_traffic_config virtual_switch=vs0
net.update_vpc_traffic_config virtual_switch=vs1
#net.update_vpc_east_west_traffic_config virtual_switch=vs0
#net.update_vpc_east_west_traffic_config virtual_switch=vs1
Second command
#net.update_vpc_east_west_traffic_config permit_all_traffic=true
net.update_vpc_east_west_traffic_config permit_vpc_traffic=true
#net.update_vpc_east_west_traffic_config permit_all_traffic=false
#net.update_vpc_east_west_traffic_config permit_vpc_traffic=false
Answer:
Explanation:
See the Explanation for step by step solution
Explanation:
First, you need to open the Prism Central CLI from the Windows Server 2019 workstation. You can do this by clicking on the Start menu and typing "Prism Central CLI". Then, you need to log in with the credentials provided to you.
Second, you need to run the two commands that I have already given you in Desktop\Files\Network\flow.txt. These commands are:
net.update_vpc_traffic_config virtual_switch=vs1 net.update_vpc_east_west_traffic_config permit_vpc_traffic=true These commands will update the virtual switch that carries the VPC traffic to vs1, and update the VPC east-west traffic configuration to allow only VPC traffic. You can verify that these commands have been executed successfully by running the command:
net.get_vpc_traffic_config
This command will show you the current settings of the virtual switch and the VPC east-west traffic configuration.
Third, you need to SSH directly to any AHV node (not a CVM) in the cluster and run the command:
ovs-vsctl show
This command will display an overview of the Open vSwitch configuration on the AHV node. You can copy and paste the output of this command to a new text file named Desktop\Files\Network\AHVswitch.txt.
You can use any SSH client such as PuTTY or Windows PowerShell to connect to the AHV node. You will need the IP address and the credentials of the AHV node, which you can find in Prism Element or Prism Central.
remove # from greens
On AHV execute:
sudo ovs-vsctl show
CVM access AHV access command
nutanix@NTNX-A-CVM:192.168.10.5:~$ ssh [email protected] "ovs-vsctl show" Open AHVswitch.txt and copy paste output
NEW QUESTION # 17
......
NCM-MCI Dumps With 100% Verified Q&As - Pass Guarantee or Full Refund: https://surepass.free4dump.com/NCM-MCI-real-dump.html